NDA available
If your company requires a confidentiality agreement before sharing sample files, that can be arranged.

Share a few sample files. I build a private application that processes your PDFs, Excel files, text files, XML, CSVs, scanned documents, and legacy exports inside your own company environment. No cloud uploads, no third-party handling, and no recurring conversion bill.
A custom application is software made specifically for your documents and your required output. You send sample files and explain the result you need. I build the application, your team tests it, and the final version runs inside your office, computer, or server.
This means your full archive does not need to be uploaded to another company. You can process files, validate results, and store the converted data on your own systems.

You share a few representative files and the output you want. The full archive can stay with you.
After delivery, the application works on your own computer, local network, or server.
Pay once for the application instead of paying another company every time files need processing.
The paid version can process full batches without the 5-file trial limit.
Send your confidential archive to an outside company.
Keep files on your own systems and run the application internally.
Pay again for every new batch, project, or repeated conversion.
Make a one-time payment for software that keeps working.
Wait for vendor queues, manual checks, and file transfer cycles.
Process files whenever your team needs them, at local machine speed.
Accept extra risk while files move between companies.
Reduce data leakage risk because production files do not leave you.
The working idea is simple: share only the samples needed to build and test the software, then keep production processing on your own systems.
If your company requires a confidentiality agreement before sharing sample files, that can be arranged.
A few representative files are enough to build the trial. Your full archive does not need to be shared.
The full application can process real business files inside your own company environment.
Use the application on a desktop computer, local machine, internal network, or company server.
Experience gained while delivering enterprise data transformation projects through my employer.
I am a Data Scientist with over 6 years of professional experience specializing in enterprise-scale legacy data conversion, extraction, cleansing, and automation. I build practical applications that help companies process their own sensitive files without sending full archives to another vendor.
Throughout my career, I have contributed to large-scale data modernization initiatives involving globally recognized organizations across the banking, manufacturing, logistics, energy, and consumer goods sectors.
My expertise includes transforming complex legacy information stored across PDFs, Excel spreadsheets, scanned documents, text files, CSV files, reports, and other structured and unstructured sources into clean, normalized, database-ready datasets and repeatable in-house processing tools.
My work helps organizations modernize legacy systems, improve data quality, reduce repeated outsourcing costs, and prepare reliable datasets for ERP systems, CRM platforms, business intelligence solutions, and SQL databases.
I have worked on projects where precision, consistency, and data integrity were business-critical, delivering clean, validated datasets for enterprise-scale migration initiatives.
Every project is delivered with a strong focus on precision, consistency, validation, and data integrity to ensure the final software and converted data are ready for immediate business use.
Experienced in processing multilingual datasets, including:
From file analysis to extraction rules, validation, output design, and in-house deployment, the service is focused on making repeat data conversion easy for your own team.
Get a private desktop or server application built around your sample files, business rules, and required output format.
Recover critical fields from legacy files, reports, exports, and archived operational records.
Convert complex PDFs into structured tables while preserving every valuable data point.
Normalize multi-sheet workbooks, inconsistent columns, formulas, and merged legacy layouts.
Parse plain text, logs, fixed-width files, and semi-structured exports into clean datasets.
Prepare validated, normalized outputs aligned to relational or analytics database schemas.
Standardize inconsistent naming, formats, missing fields, duplicate rows, and noisy values.
Apply rule-based checks, cross-field validation, completeness review, and anomaly detection.
Clean OCR outputs from scanned PDFs and images for accurate downstream processing.
Process English, German, French, and additional European document conventions.
Set up the final application so your team can process and archive data on your own systems.
Create consistent tables with clean headers, formats, field mapping, and referential clarity.
Run final checks for integrity, consistency, completeness, and delivery-readiness.
The trial application proves the logic on real files. The full application removes the trial limit and lets your team process future batches whenever needed.
Step 1
Step 2
Step 3
Step 4
Step 5
Step 6
Step 7
Step 8
This is best for teams that have sensitive files, repeated manual conversion work, large archives, or vendor quotes that feel too high for a repeatable task.
For companies with large archives of PDFs, Excel workbooks, text reports, XML files, scans, or legacy exports.
For teams that cannot safely send production files to outside processors or online conversion tools.
For businesses that receive the same file type again and again and need a faster repeatable workflow.
For organizations being asked to pay large recurring fees for conversion work that software could automate.
For teams spending hours opening files, copying values, correcting formats, and preparing spreadsheets.
The trial is free and limited to 5 files at a time. Once the result is approved, the paid version is built for ongoing in-house use.

Explore the most common legacy data migration challenges, from inconsistent source formats and OCR cleanup to duplicate records, missing identifiers, and data validation.
Read more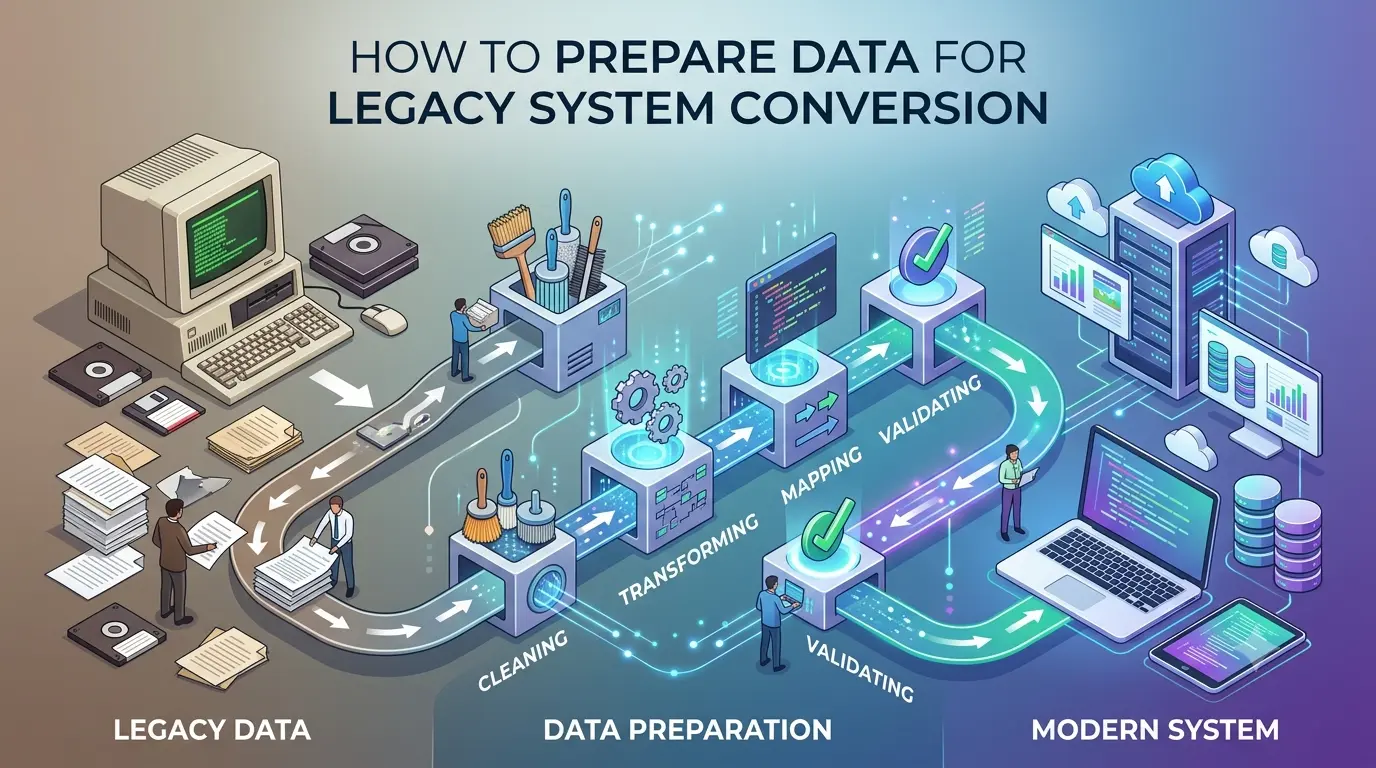
Learn how to prepare source files, field mappings, validation rules, and document samples before starting a legacy system conversion project to ensure accurate and efficient data migration.
Read more
Discover the complete PDF to database conversion process, from analyzing documents and extracting data to validation, cleansing, and database import. Learn best practices for accurate and reliable data conversion.
Read more
Learn what legacy data conversion is, why businesses need it, how the process works, and how legacy information is transformed into clean, structured, database-ready data.
Read moreWhat our customers are saying about the service and experience.
"The delivered datasets were exceptionally clean and accurately structured. The level of detail exceeded expectations."
Operations Manager
Manufacturing Sector
"Outstanding data transformation quality. Complex legacy files were converted into perfectly organized database-ready tables."
Senior Business Analyst
Financial Services
"The professionalism, precision, and communication throughout the project were excellent."
Project Lead
Enterprise Solutions
"One of the most accurate data extraction services we've experienced."
Data Migration Consultant
Technology Industry
Years Experience
Data Integrity Focus
Records Experience
Payment for Full Application
It is a private application built for your exact files and output format. You use it inside your own company to convert, validate, and archive data without sending production files to an outside vendor.
You send sample files and requirements. I build a trial application for your format, free of charge, with one limit: it processes up to 5 files at a time.
No. The full application can run on your own computer, local network, or server, so your production files and archived data stay inside your environment.
Yes. The full custom application is delivered for a one-time payment, so you do not keep paying per file, per batch, or every month for the same conversion work.
The paid version can be designed for high-volume batch processing without the 5-file trial limit. Practical speed depends on file complexity and the computer or server used.
Yes. I can extract and transform data from scanned PDFs using OCR and advanced data extraction techniques.
I work with a wide range of file formats including PDF, TXT, XLSX, XLS, CSV, XML, JSON, DOCX, HTML, databases, and many other structured or unstructured file types.
For custom software, you provide sample files and your required output. I analyze the structure, build the trial application, validate the output with you, and then deliver the full application for in-house use.
The free trial application lets you test the conversion on up to 5 files at a time before you approve the full version.
If any issues are found that are within the agreed project scope, I will correct them promptly. Client satisfaction is a priority, and reasonable revisions are included.
Sample files are used only to build and verify the application. Once the project is complete and you confirm the result, project files are deleted unless you request otherwise.
Yes. I have experience processing documents in English, German, French, and other languages depending on the project requirements.
Yes. I can deliver clean, validated, structured data ready for import into SQL databases, ERP systems, CRM platforms, and other business applications.
Yes. I have experience with enterprise-scale data work and can design applications for very large archives, including millions or billions of records, when the source files and infrastructure support it.
Upload up to 5 sample files and describe the output you need. I will review the structure and build a trial application that processes up to 5 files at a time, so you can verify the result before paying for the full version.
contact@legacydataconversion.com